Agentic AI in contact centers can investigate orders, check policies, propose remedies and, when permitted, update business systems. This article explains the decision context, authority checks and staged autonomy needed to resolve customer issues within policy and with evidence for every decision.
Agentic AI can take a contact center beyond answering customer questions. It can investigate an order, check a policy, propose a remedy and, when permitted, update business systems. That opportunity also changes the risk: a fluent response may be harmless, while an unauthorized refund or account change has a direct customer and financial impact.
The practical goal is governed resolution: resolve the issue, stay within the agent’s authority, and retain enough evidence to explain the decision. This article maps the data, execution and approval layers needed to do that, then shows how a team can expand autonomy based on measured results.
See how Context OS governs AI agent decisions
Context OS gives contact center agents current, permitted context and checks authority before any refund or account change executes.
Why Agentic AI in Contact Centers Needs Decision Context
A service request spans more than the conversation. Customer history may be in CRM, charges in billing, delivery events in an order system, entitlements in contracts and exceptions in policy documents. Contact center platforms handle channels and routing, but an agent needs a coherent view of these records before it can decide what action makes sense. Amazon Connect Customer Profiles documentation illustrates the value of bringing contact history and customer information into the agent workflow.
Suppose a customer says a promised refund has not arrived. A lookup of the refund policy alone might suggest creating another refund. Decision context should also show the prior promise, an open refund request, its current status and the processing window. Freshness and provenance matter because a correct policy applied to stale account data can produce the wrong action.
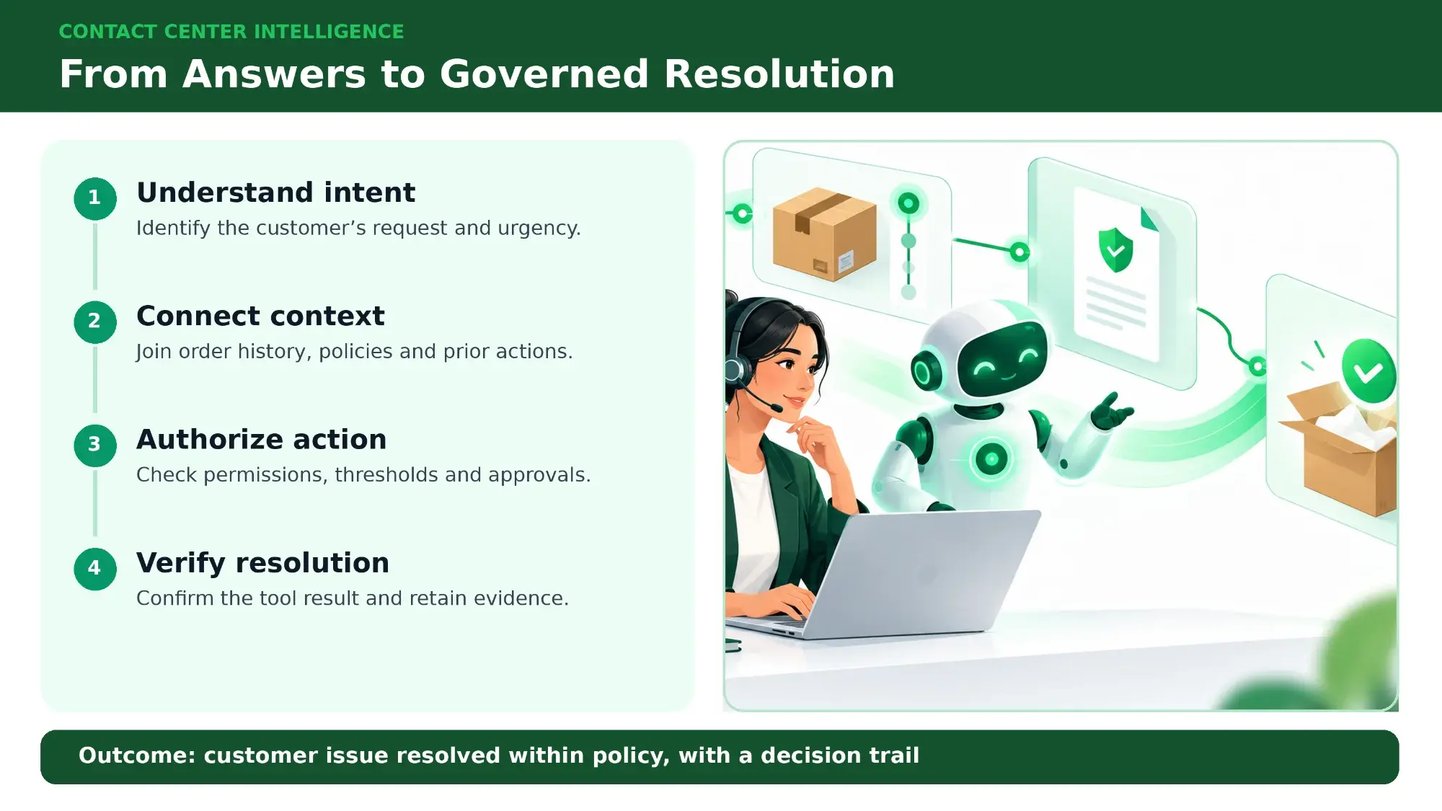
Figure 1. From intent to a verified resolution within policy.
From Conversation to Governed Action
Rule-based automation follows a prescribed path. Generative AI can summarize a case or recommend a reply. An agentic system can coordinate multiple steps and call business tools. Google Cloud’s Agent Assist documentation provides an example of AI assisting human contact center agents; autonomous execution adds the separate requirement to check whether the proposed transaction is allowed.
A useful sequence is: detect customer intent; assemble current context; propose an action; evaluate identity, policy and limits; obtain approval if needed; execute through a scoped tool; verify the result; and retain a decision trace. The authority check must occur before execution. A prompt that says “never refund more than $500” cannot substitute for a control at the transaction boundary. OWASP’s excessive agency guidance explains why tool access and permissions need limits.
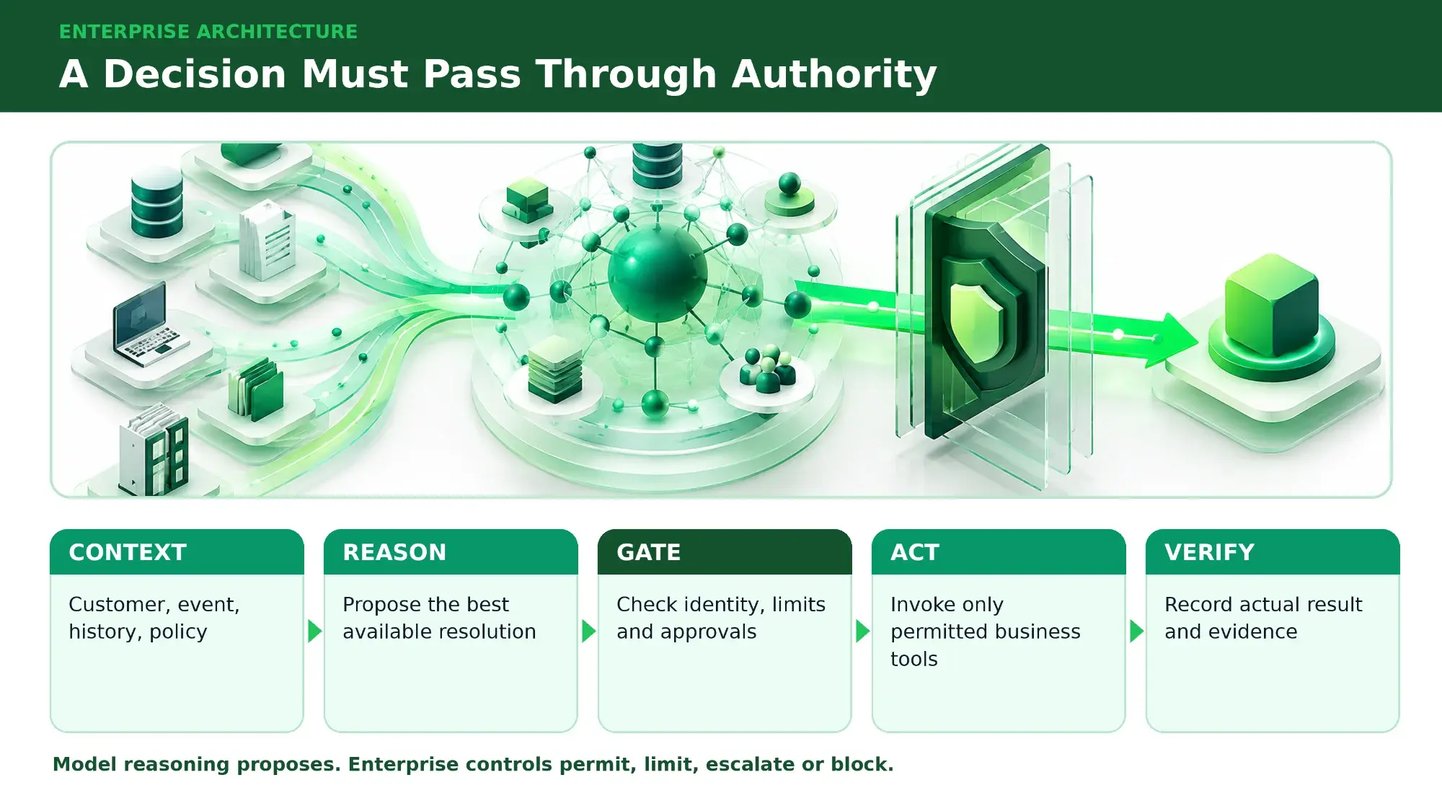
Figure 2. A proposed action passes an authority gate before execution
How the Architecture Separates Responsibilities
ElixirData supplies decision-ready context
ElixirData Context OS can connect customer, account, subscription, order, policy and prior decision records, including their relationships and timestamps. A context graph helps an agent see that a damaged item belongs to a particular order, that the order has a delivery exception and that a concession was already made. Context retrieval must still honor the requesting identity and source permissions.
ElixirClaw governs agent execution
ElixirClaw Agentic OS manages the runtime side: agents, connectors, tool invocation, decision boundaries, approvals and operational traces. The model may recommend a replacement and delivery refund. Before a tool acts, the execution layer should confirm customer identity, eligibility, value limits, inventory and any fraud or compliance flags. The outcome may be allow, modify, escalate or block.
ElixirHub manages reusable skills
ElixirHub is the reusable skill registry described in the Elixir platform architecture. Contact center teams can version skills for identity verification, refund eligibility, case summarization or escalation preparation and reuse them across agents. The registry manages the skill lifecycle; runtime permissions and execution remain with ElixirClaw. A specialized fraud or churn model can be invoked as a controlled tool, with its score treated as one piece of evidence rather than an automatic decision.
Specialized models inform decisions
Some contact center tasks need purpose-built models rather than another general language-model response. Fraud classifiers can flag an unusual refund pattern; churn models can estimate the likelihood that a customer may leave; forecasting can anticipate queue pressure. The output should be interpreted in the context of the specific customer and the model’s limitations. A risk score alone should never authorize a payment change or deny service. Record the model version and relevant score when they materially affect a decision.
Keep the operating roles clear as the architecture grows: the contact center platform owns channels and routing; the context layer assembles permitted facts; reusable skills package procedures; and the agent runtime coordinates approved tools. Analytics over the resulting decisions can show which policies drive manual work and which customer journeys produce repeat contact. This separation makes it easier to update a model or a procedure without silently expanding an agent’s authority.
Example A Damaged and Late Retail Order
A customer reports that an item arrived damaged four days late and is needed tomorrow. A basic chatbot can quote the returns policy. A governed agent can check the order, delivery event, replacement stock, customer history, previous concessions and applicable policy before proposing a practical remedy.
-
Understand: identify the damaged item, late delivery, deadline and desired remedy.
-
Compare: assess local pickup, fast replacement, delivery-fee refund and escalation.
-
Authorize: check identity, stock, compensation ceiling and exception rules.
-
Act and verify: reserve an available item, issue an allowed adjustment and confirm pickup instructions.
If the order falls outside the policy or the proposed amount exceeds the agent’s authority, route a concise case to a human reviewer. The reviewer should see the proposed action, underlying evidence and policy result. Retain the final decision, any override, the tool calls and customer outcome so the case can be reconstructed later.
This example depends on several checks that are easy to overlook. An inventory record must indicate that the replacement can actually be collected before tomorrow. The delivery charge adjustment must not duplicate an earlier concession. The message to the customer should describe only actions that completed successfully. If reserving the item succeeds but the refund API times out, the system must reconcile the transaction before retrying, rather than assume that an error means no money moved.
Get the Executive Blueprint for governed enterprise AI
A practical guide for CIOs, CAIOs and risk leaders on moving AI agents from pilot to production without losing control of context or decisions.
Choose Use Cases by Operational Value and Risk
Frequent requests that cross several systems are promising candidates: refunds and returns, billing corrections, order exceptions, appointments, claims intake and complex agent assist. Start with a narrowly defined intent and a measurable outcome. A billing agent might explain a disputed charge automatically but require approval to reverse it. An insurance intake agent might gather documents and open a case while leaving coverage decisions to a qualified reviewer.
The selection test is whether the organization can define the information required, the action boundary and a reliable verification step. If source records are incomplete or the rule depends on nuanced discretion, begin with agent assist. XenonStack’s contact center agentic AI use cases offers additional workflow examples; each needs its own authority model.
A use case scorecard can compare the request volume, current handling effort, number of systems involved, cost of a wrong action and quality of the available records. A high volume status query may be easy to automate but deliver limited new value. A complex billing exception may offer greater value, yet should begin with human approval because a wrong adjustment could be consequential. This keeps pilot selection grounded in customer outcomes and operational feasibility.
Expand Autonomy in Stages
Autonomy is better granted by intent than switched on for the whole contact center. In shadow mode, the AI recommends a remedy without acting. In supervised mode, a person approves its proposed action. In bounded mode, it executes only within explicit limits. Full end-to-end execution is reserved for intents that meet performance and control thresholds, with monitoring and escalation still active.
Promotion should use sampled decision traces, policy test results and customer outcomes. A high agreement rate with human agents is useful but insufficient if the human process itself is inconsistent. Test edge cases: duplicate refunds, stale data, identity mismatch, prompt injection in a customer message and tool failures. NIST’s AI Risk Management Framework offers a useful structure for governing, mapping, measuring and managing these risks.
Set a promotion gate for each intent. Define the eligible customer segment, maximum transaction value, required evidence and rollback plan. Review a sample of correct and incorrect outcomes with service operations, risk and engineering. If the agent repeatedly asks humans to decide cases that should fit within its scope, improve the underlying context or clarify policy before expanding authority. If it acts correctly only when records are pristine, keep its limits narrow.
Design for Privacy Security and Exception Handling
Customer conversations often include identity details, payment information and other sensitive data. Give each agent a scoped identity; filter retrieval by source permissions; minimize the data sent to models; and restrict logs to what investigators genuinely need. Where a provider or hosted model processes customer content, assess retention, access, residency and contractual controls before deployment. A private inference environment can address some exposure concerns but does not replace transaction authorization or data quality checks.
Treat messages, attachments and retrieved documents as untrusted input. An attacker can put instructions in a customer message or knowledge article that attempt to redirect an agent toward another account or tool. The runtime should prevent untrusted text from becoming system authority, limit available tools and require policy checks for sensitive actions. Test these paths against actual workflows, including handoffs between agents and failures of an external service.
Design an exception path before enabling automation. A blocked request should produce a useful explanation for the employee without exposing sensitive policy details to a customer. The case packet should include the customer intent, facts retrieved, proposed remedy, reasons for escalation, missing evidence and any work already performed. The human should be able to correct the record, approve an allowed exception or decline the request without reconstructing the case from scratch.
Measure Governed Resolution
Containment rate counts conversations that did not reach a human. It does not show whether the customer’s problem was solved. Track governed resolution instead: a valid action, within policy, with a confirmed outcome and no avoidable repeat contact. Review it alongside customer satisfaction, repeat contact, escalation accuracy, policy exceptions, override rate, decision trace coverage and cost per resolved case.
Separate metrics by intent and autonomy level. A blended headline can hide a failure in a sensitive workflow. Investigate denied actions as well as successful ones: frequent blocks may reveal poor context, unclear policy or an agent that is attempting too much. Human reviewers remain essential for emotional, unusual or high consequence cases and for improving the boundaries over time.
Close the learning loop with a weekly review of repeat contacts, overturned decisions and escalations. Categorize why a decision failed: missing source, stale source, ambiguous policy, incorrect reasoning, tool error or insufficient authority. Each category points to a different fix. Update a skill when a procedure is inconsistent, improve the context layer when records are incomplete, and adjust a runtime boundary only after the business owner accepts the change.
Conclusion
The contact center becomes a reliable decision system when agents receive current context, actions pass independent authority checks and outcomes can be verified. Start with a bounded intent, preserve human control for exceptions and expand autonomy only when evidence shows that the workflow resolves customer issues correctly and within policy.
Take the next step
Download the Executive Blueprint, or talk to our team about governed agentic AI for your contact center.
ElixirData: Frequently Asked Questions
-
What is agentic AI in a contact center?
It is AI that can coordinate steps across systems and execute approved customer-service actions, not only generate replies. -
Why does a contact center agent need a context graph?
It connects customer, order, entitlement, policy and prior outcome records so the agent can assess the full situation. -
Can an AI agent issue a refund automatically?
Yes, when identity, eligibility and transaction limits are checked before execution and the intent is approved for automation. -
When should a human review an AI decision?
Use review for policy exceptions, high value actions, uncertain evidence and sensitive or irreversible outcomes. -
Which metrics matter beyond containment?
Measure valid resolution, repeat contact, policy conformance, escalation accuracy, customer outcome and trace coverage.